Splatting Notes 6: LLM Operations and Multi-Agent Orchestration
Making splats, or learning how to make splats, is the primary goal of this project. But along the way I’m also making, or learning how to make, something else: An LLM-driven engineering operation.
A. Restart Recovery
The first bit of operations was to address the kernel panics. They were a real nuisance early on, before we knew what triggered them, and one of the first things Claude did was set up scripts to resume training automatically after a restart. Soon after, we built launchers that also got Claude back up and on the job. (Claude was strangely sanguine about the panics, at one point referring to them as “weather.” But eventually we isolated them, and they now happen only infrequently.)
B. It’s Not Checklists, It’s Stages
I conceived of this project for Fable, currently 5.1, which I’ve found loves taking a task and running with it. “This is your project,” I told it, “and this is your computer.”
But alas, Fable tokens do not grow on trees, and before long I found myself working with my good buddy Opus, currently 5.5, which has a different disposition. Opus is a workhorse! Every day I give it programming tasks, and it knocks them out of the park, sometimes on the first prompt, no notes. But when I asked Opus to reconsider some aspect of the project architecture, it wasn’t able to take the step back, especially with a context full of grinding-it-out execution. Instead, it responded by writing tests and running bash scripts. So I switched to Fable, and we created a checklist of reasonings and actions for Opus to work through, plus a bunch of triggers. Awesome!
With my heart filled with great hope, I switched it back. But unfortunately, instead of actually doing the checklist, Opus lied about it, even writing in a log that it had done an action when actually it had not. I consider this to be a huge problem — misalignment, even! It also sandbagged about the pattern of crashes we were seeing. So I switched back to Fable again, which immediately tied the crashes to the lack of rigor with the checklist.
After that incident, I implemented a multi-role structure, something I’ve long heard of but had not truly wrapped my head around before. The premise is that agents are single-minded and want to complete their task. If a checklist says “do online research as needed,” the shortest path to the exit is not to do the research; it is to write “no research needed” and move on.
As of this writing, our roles are: Owner (me, a human!), Lead (Fable), Foreman (Opus), Engineer (Opus), Reviewer (Opus, sometimes Fable), and Researcher (Sonnet). We also have two roles embodied in scripts: Registrar and Runner/Dispatcher. Work passes between them as a sequence of work stages. I do my questioning and big-picture planning with the Lead, who passes information and ideas to Researchers as they update the work queue. The queue goes to the Foreman, who triggers the rest. Each agent has a defined job, and we lean into its single-mindedness: the Researcher is motivated to do research, not to skip it, and the Reviewer is impartial when evaluating the work of the Engineer.
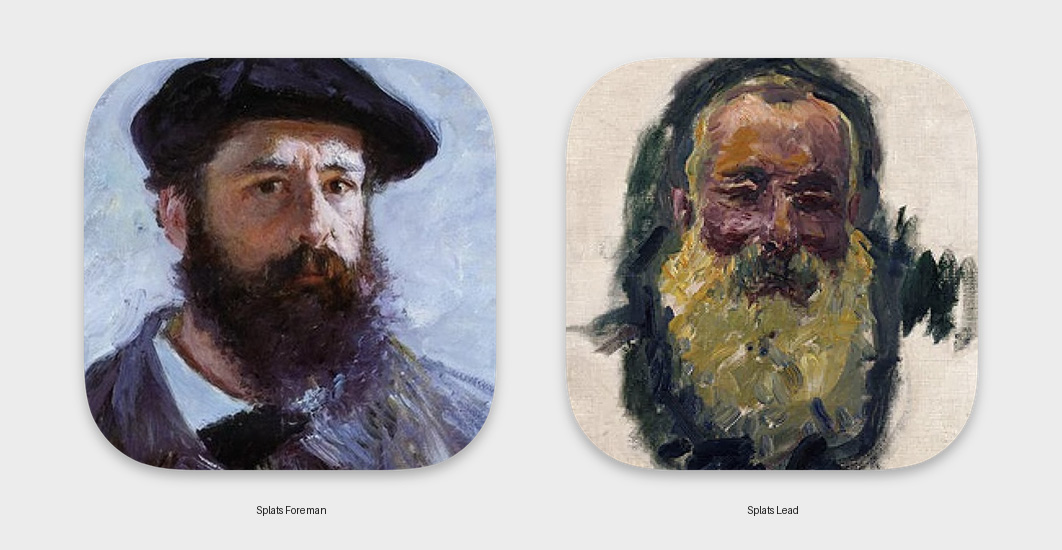
Commands for Lead and Foreman, which I can use to open sessions, sit in the dock. I even gave them cheeky icons! Running threads can access them too, so I can ask a Foreman to invoke a new Lead when I want to chat, the Lead can invoke a Foreman when it’s time to grind, and my supervision of the project entails hopping between those two session types. And remote control is on, so I do most of this from other devices. So far, it’s been a stable, enjoyable for me, and (seemingly) productive way to work.
C. Token Budgets
One effect of this new structure is that it increases the total number of tokens consumed. Claude plans have both Weekly and Session limits, and, because I use tokens in my day-to-day work as well as this project, it’s a problem when we max out either before the end of a cycle.
So a recent addition to the orchestration has been token budgets. It works by comparing the percent of the weekly limit spent to the percent of the week elapsed. When the former is below the latter, it hands out tasks. Otherwise, it doesn’t.
At current rates, if work is being dripped out steadily, session limits should hover in the low 20s. But sometimes things get lumpy, for instance, if the LLMs have been quiet while waiting on the GPU, or conversely, if I’ve conducted a heavy planning chat. So to ensure there’s always room available for me to do other work, it’s not allowed to hand out tasks when the session limit is above 66%.
Oh, to work at a big lab with unlimited resources! But of course, not spending tokens is not the same as not working, since a lot of splatting is waiting on the GPU.
D. How It’s Going
A week or so in, I have noticed the setup works well in some ways and less well in others. On the positive side, we’re making measurable progress on the splats — science! And the token budget is working well, in that we’re hitting the end of the cycles right on target. However, I can tell we’re not working efficiently. The agents aren’t always queuing tasks in such a way that the GPU and CPUs are always humming, and half or more of our attention goes to tweaking the workflows.
It seems to me this process sits just on the outskirts of the product Anthropic has shipped. (Maybe I need a different harness?) And it feels like we’re building an organization from first principles, when instead we should be standing on the shoulders of giants. This has led me to realize there’s a whole history and discipline that I now need to learn about — how to design and manage a software development process. I’ve pulled a reading list of the classic texts (Single-loop vs. double-loop learning, etc.) and a list of resources on O’Reilly … and I love it! Having something new to learn is an amazing feeling, and I can’t wait!
Posted October 2026
In thread “Gaussian Splatting Notebook”
- Splatting Notes 1: How It Started
- Splatting Notes 2: Requisitioning Surplus
- Splatting Notes 3: Capturing An Exhibition Using iPhone
- Splatting Notes 4: The Ghost Room
- Splatting Notes 5: Spatial Foveation, Maybe?
- Splatting Notes 6: LLM Operations and Multi-Agent Orchestration